What Is Self-Attention?
Self-attention is attention applied inside one sequence. Each token builds a better representation by comparing itself with the other tokens in the same input.
Evaluation, inference, model products, and applied AI systems.
Self-attention is attention applied inside one sequence. Each token builds a better representation by comparing itself with the other tokens in the same input.
Attention changed the sequence-model bottleneck. Instead of forcing every old clue through one running state, it let the model look back and score which earlier tokens mattered now.
RNNs and LSTMs gave language models memory, but that memory still had to pass through one step after another. Long context made useful clues fade, compete, and arrive too slowly.
Plain RNNs rewrote one hidden state at every step. LSTMs added gates and a cell state, giving the model a cleaner path for preserving useful information over longer spans.
RNNs improved on local n-gram counting by carrying a hidden state through the text. The tradeoff was dependency: token 10 cannot be processed until token 9 has updated the state.
N-gram models were useful because they turned language into counts. They failed because a fixed local window cannot remember distant context, understand meaning, or generalize well to unseen phrases.
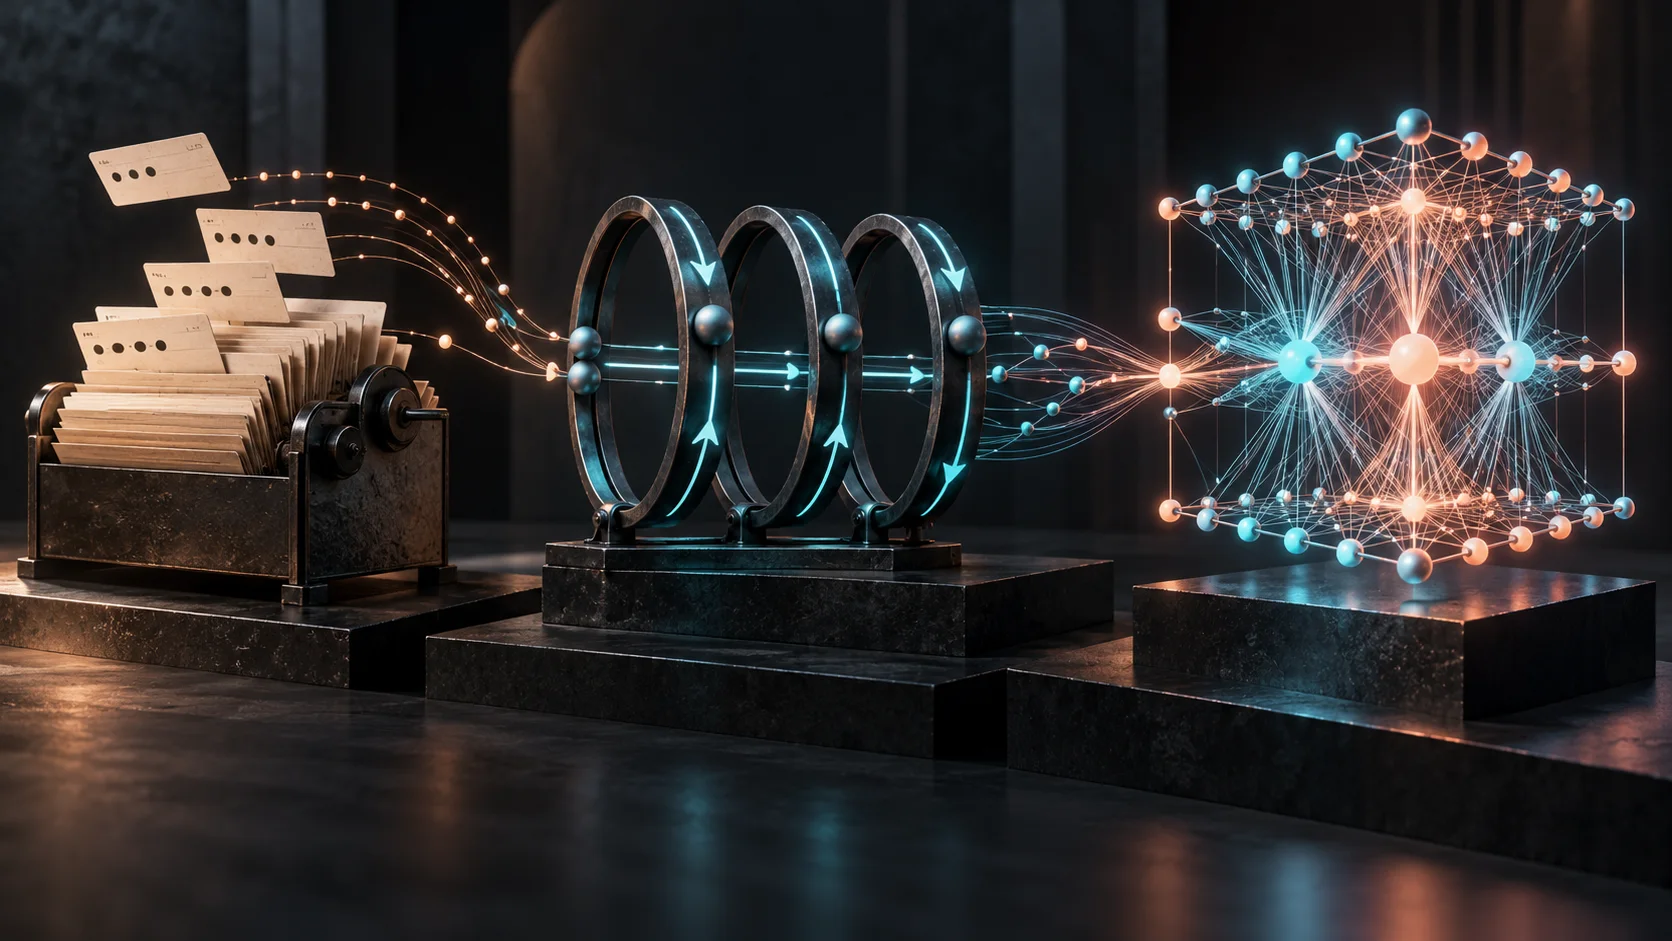
Transformers were not the first attempt to model language. They arrived after rules, n-grams, recurrent networks, LSTMs, seq2seq models, and attention exposed the same bottleneck: sequence processing was too slow and too forgetful.
Before transformers, KV cache, and GPU serving, language models had a smaller job: look at context and predict what text should come next.
Speculative decoding speeds up LLM inference by letting a cheap draft model guess several tokens, then asking the expensive target model to verify those guesses in one parallel pass.
If language models can be compiled directly into silicon, inference stops looking like software running on a GPU and starts looking like the computer itself.
Bigger GPUs help, but fast LLM serving is mostly a scheduling and KV cache problem. PagedAttention, block allocation, batching, and prefix caching decide how much useful work fits in memory.
VRAM planning for LLMs is not just about model weights. Long context windows can make the KV cache as expensive as the model itself.