The Hidden VRAM Bill Behind Long Context
VRAM planning for LLMs is not just about model weights. Long context windows can make the KV cache as expensive as the model itself.
Short notes on the practical constraints that shape model serving.
Start first articleVRAM planning for LLMs is not just about model weights. Long context windows can make the KV cache as expensive as the model itself.
Bigger GPUs help, but fast LLM serving is mostly a scheduling and KV cache problem. PagedAttention, block allocation, batching, and prefix caching decide how much useful work fits in memory.
If language models can be compiled directly into silicon, inference stops looking like software running on a GPU and starts looking like the computer itself.
Analytical databases like BigQuery and Redshift are fast because they stop pretending every query needs every field. They read columns, compress patterns, and skip the bytes your question never asked for.
Before KRaft, Kafka used ZooKeeper as its coordination layer: broker membership, controller election, topic metadata, partition leaders, and ISR state all needed a consistent place to live.
Speculative decoding speeds up LLM inference by letting a cheap draft model guess several tokens, then asking the expensive target model to verify those guesses in one parallel pass.
Before transformers, KV cache, and GPU serving, language models had a smaller job: look at context and predict what text should come next.
Transformers were not the first attempt to model language. They arrived after rules, n-grams, recurrent networks, LSTMs, seq2seq models, and attention exposed the same bottleneck: sequence processing was too slow and too forgetful.
N-gram models were useful because they turned language into counts. They failed because a fixed local window cannot remember distant context, understand meaning, or generalize well to unseen phrases.
RNNs improved on local n-gram counting by carrying a hidden state through the text. The tradeoff was dependency: token 10 cannot be processed until token 9 has updated the state.
Plain RNNs rewrote one hidden state at every step. LSTMs added gates and a cell state, giving the model a cleaner path for preserving useful information over longer spans.
RNNs and LSTMs gave language models memory, but that memory still had to pass through one step after another. Long context made useful clues fade, compete, and arrive too slowly.
Attention changed the sequence-model bottleneck. Instead of forcing every old clue through one running state, it let the model look back and score which earlier tokens mattered now.
Self-attention is attention applied inside one sequence. Each token builds a better representation by comparing itself with the other tokens in the same input.
Redis, Flink, databases, and Bloom filters can all remove duplicates, but they are not interchangeable. The right choice depends on where the duplicate appears, how long you must remember it, and what happens if you are wrong.
Resolution is only the pixel count. The picture also needs enough bits to describe those pixels. A 4K stream can have more pixels than a theater image and still give each pixel far less data.
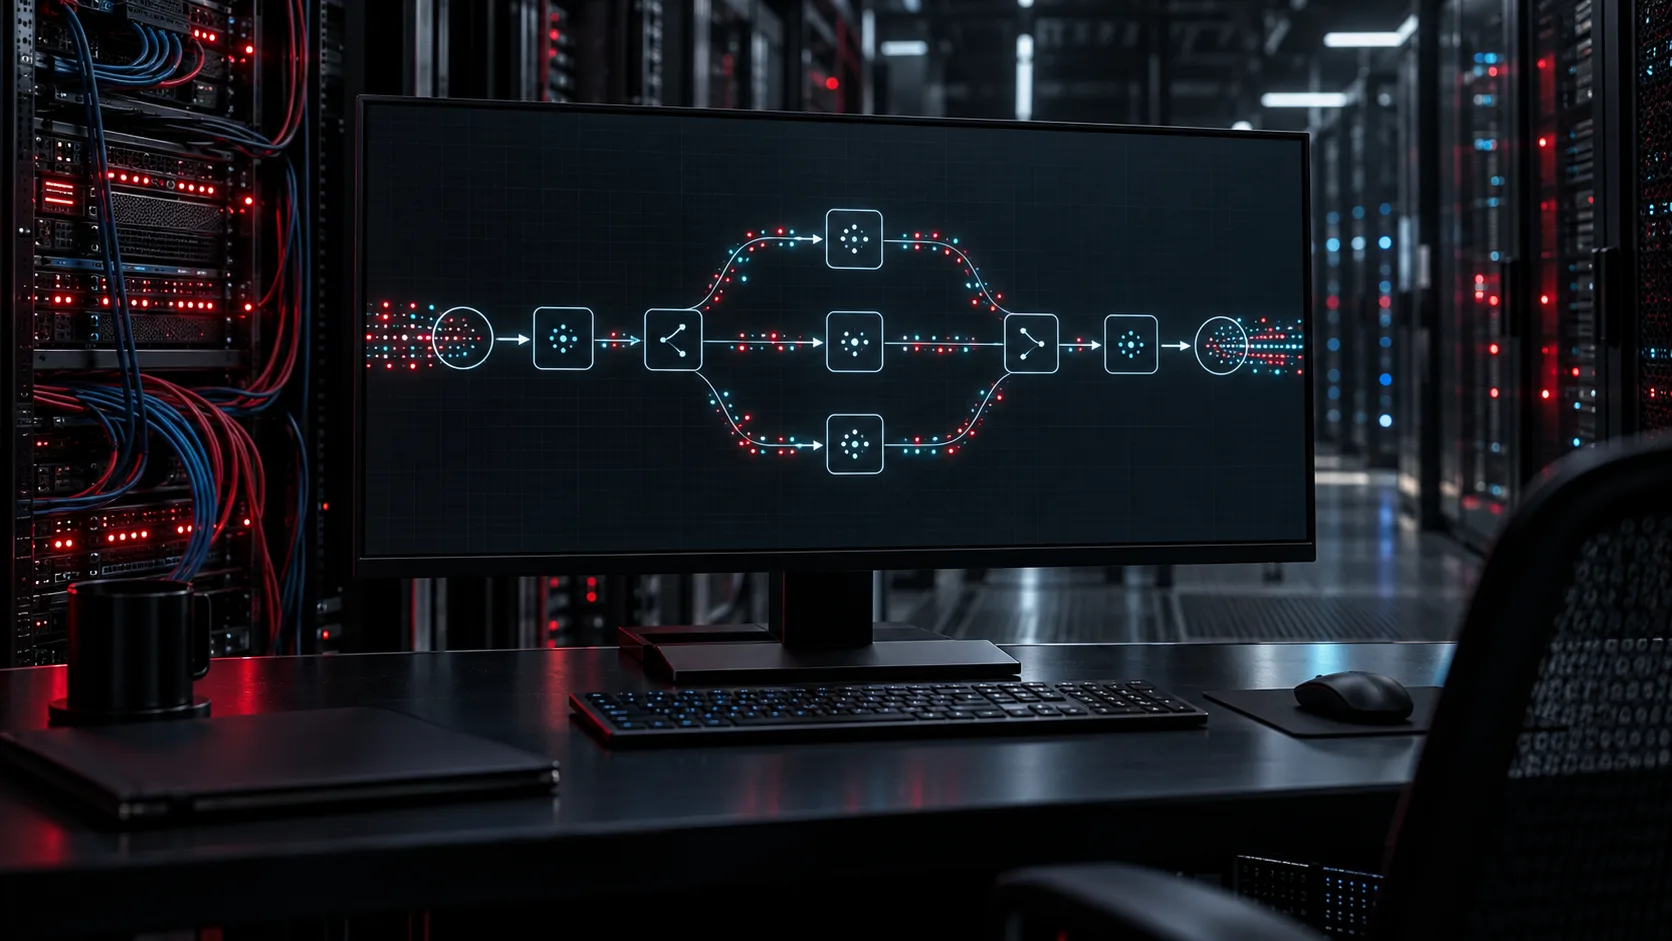
Flink is not just a library that runs a loop over events. It turns a streaming program into a distributed dataflow, splits operators into parallel subtasks, places those subtasks into task slots, and keeps state recoverable with checkpoints.
OpenAI kept one PostgreSQL primary alive for a massive read-heavy workload by moving reads to replicas, pooling connections, protecting caches, rate limiting spikes, and pushing write-heavy workloads elsewhere. The useful lesson is not "Postgres scales forever." It is knowing which pressure you are actually under.