EXPLORE THE LIBRARY

Data Engineering

Storage, warehouses, pipelines, and analytical systems.

10 min read

How OpenAI Scaled PostgreSQL to 800M Users, and What to Do in Your System

OpenAI kept one PostgreSQL primary alive for a massive read-heavy workload by moving reads to replicas, pooling connections, protecting caches, rate limiting spikes, and pushing write-heavy workloads elsewhere. The useful lesson is not "Postgres scales forever." It is knowing which pressure you are actually under.
9 min read

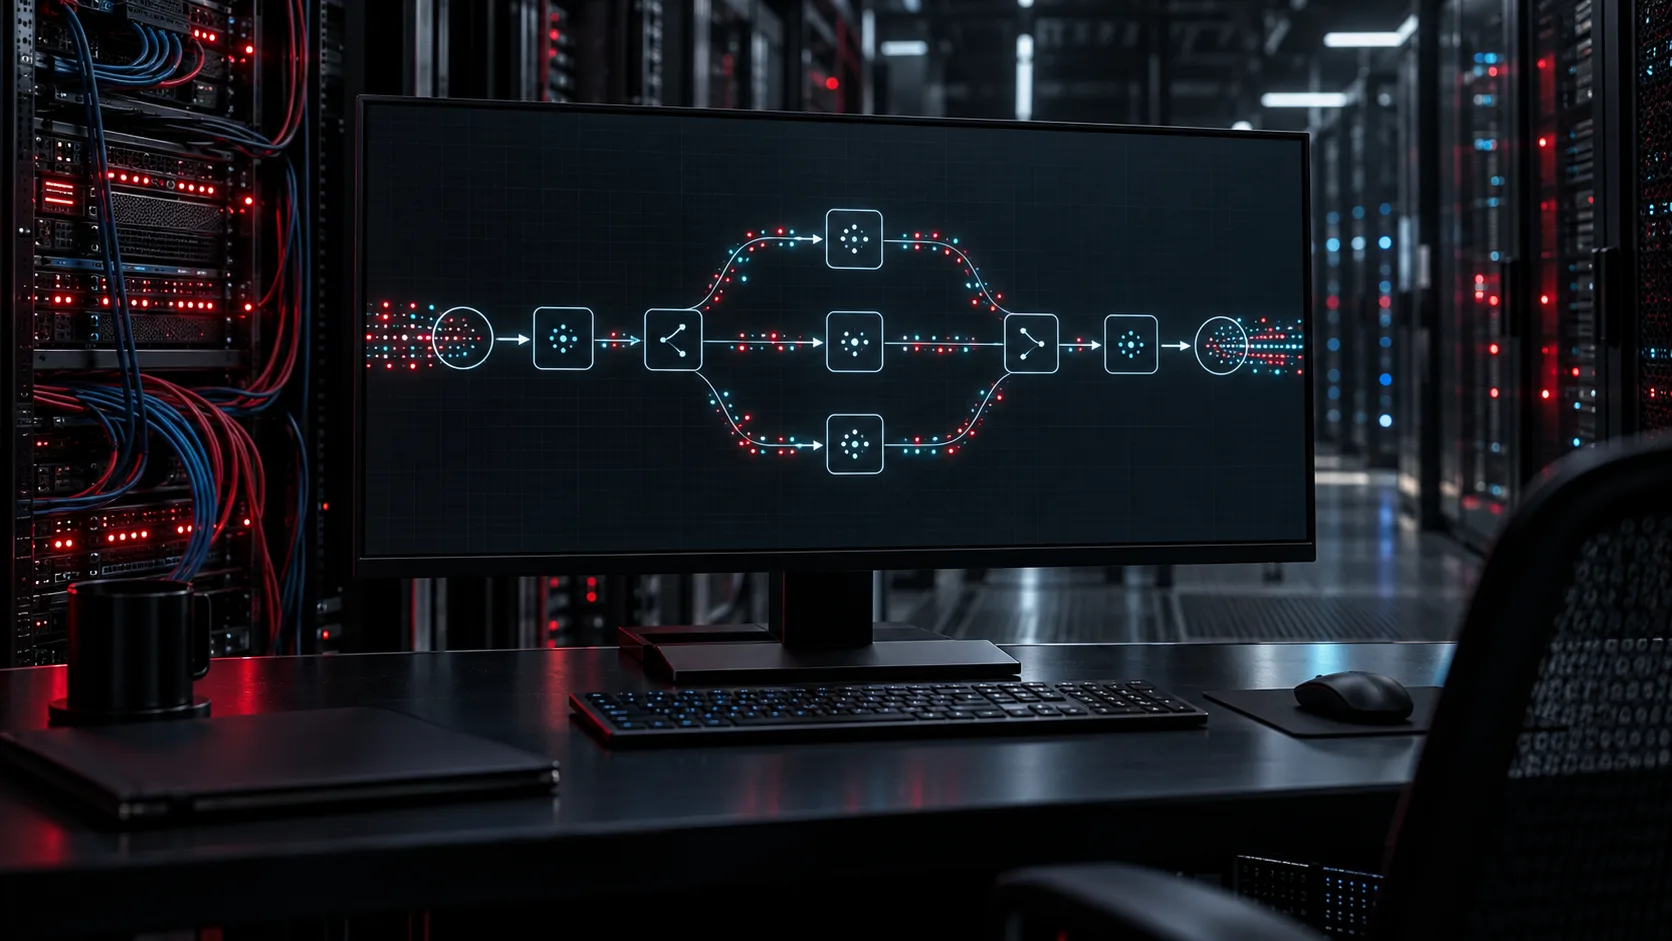
How Flink Works Internally

Flink is not just a library that runs a loop over events. It turns a streaming program into a distributed dataflow, splits operators into parallel subtasks, places those subtasks into task slots, and keeps state recoverable with checkpoints.

8 min read

How to Deduplicate Streaming Events at Scale

Redis, Flink, databases, and Bloom filters can all remove duplicates, but they are not interchangeable. The right choice depends on where the duplicate appears, how long you must remember it, and what happens if you are wrong.

6 min read

Why Kafka Needed ZooKeeper

Before KRaft, Kafka used ZooKeeper as its coordination layer: broker membership, controller election, topic metadata, partition leaders, and ISR state all needed a consistent place to live.

5 min read

Why Columnar Databases Feel Like Cheating

Analytical databases like BigQuery and Redshift are fast because they stop pretending every query needs every field. They read columns, compress patterns, and skip the bytes your question never asked for.

Menu